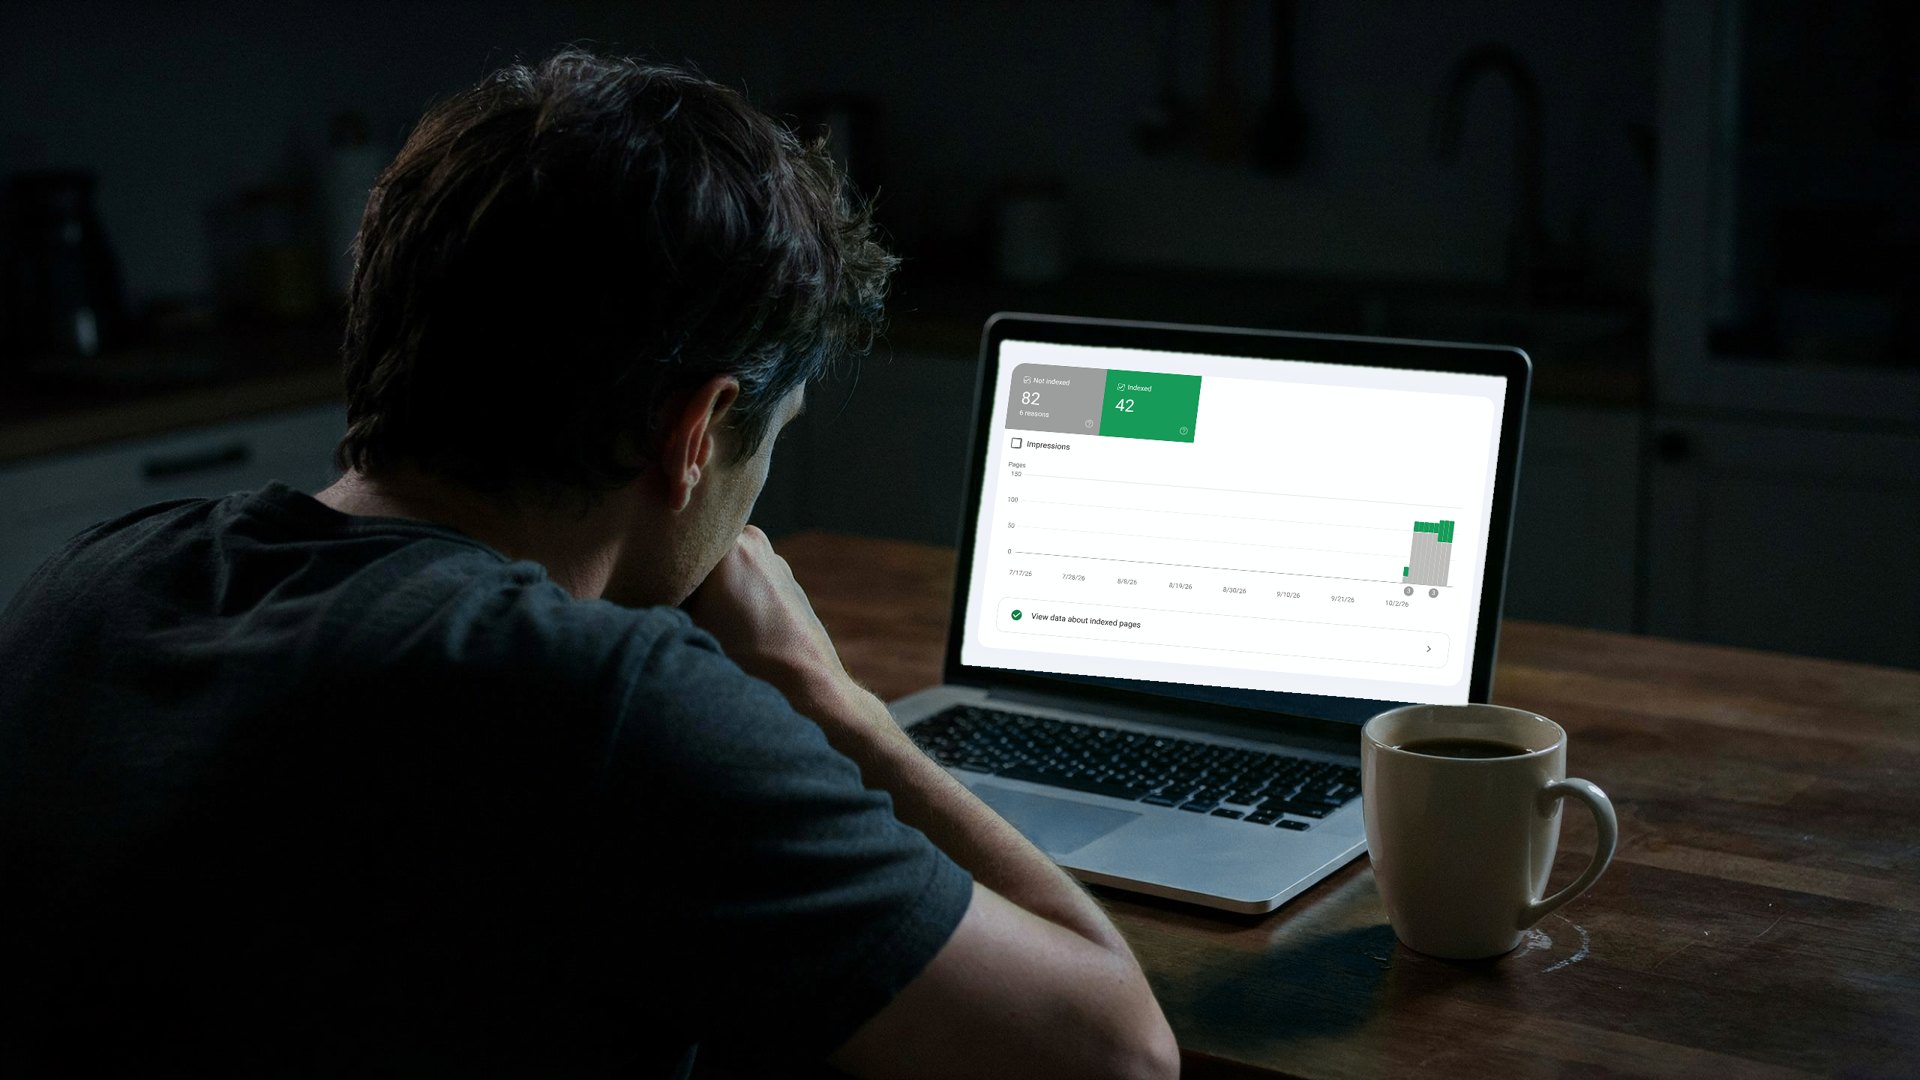
Real dates from the URL Inspection API: one site went from 1 to 24 indexed pages in six hours, another from 19 to 80 in eight days. What decides the wait.
How Long Does It Take Google to Index a Page? The Short Answer
Let’s get one thing straight: “it depends” is not an answer to how long does it take google to index a page. Here is mine. A page with nothing broken, that serves the purpose it was made for, gets indexed within about 48 hours of a Request Indexing click. Real rankings follow two to five weeks later, unless the domain already had traffic, authority or a content history. Is 48 hours my measured number? No. It is my experience from other sites, and I have not measured it yet on the two sites in this column. I label it as experience and I keep it there until the dates say otherwise.
What I have measured is the thing that decides whether the 48 hours ever starts. On every page I have watched stall, the cause was checkable the same day: a sitemap naming the wrong address, a canonical pointing somewhere relative, a noindex somebody forgot, or a page nothing on the site links to. None of those are a waiting problem. They are a Tuesday-afternoon problem.
The official answers are honest and useless at the same time. Google’s own crawling and indexing documentation says a crawl can take anywhere from a few days to a few weeks and that Google does not guarantee it will crawl, index or serve any page. In the Search Central community, the Product Expert barryhunter answered a new site owner asking this exact question with “anywhere between a few minutes and frankly never”, and I agree with him; I just think the range is wide because nobody separates the sites with something broken from the sites with nothing broken.
So this column separates them. Two of my sites, two shapes. flowingkhaos.com went from 1 indexed page to 24 in six hours, and Google did not crawl a single page in those six hours. clevrstart.com went from 19 to 80 in eight days, and Google did come back, on dates I can show. Then five pages on clevrstart that have been stuck since August, with a clock I have not started yet. Every number below comes from the URL Inspection API, read per URL, with the time of the read.
Why Google Gives You No Number, and What Is Being Counted
According to Google’s guide to how Search works, there are 3 stages, crawling, indexing and serving, and the guide shows that a page can fall out at any of them. I agree, and it is the first thing I check. The reason you get no number is that the number depends on which stage your page is stuck at, and the dashboard total does not tell you.
Here is what I mean.
According to Google’s Page indexing report help, the report shows the indexing state of every URL Google knows about on the property, and I read that word as the whole explanation. Every URL. For a domain property that means www and bare, http and https, the French tree, every subdomain and every path Google ever fetched. On 2026-10-15 that report for clevrstart.com said 82 pages were not indexed. The same afternoon my script asked the URL Inspection API about each of the 105 URLs in the sitemap, and 25 were not indexed.
| Source, 2026-10-15 | Population | Not indexed |
|---|---|---|
| Page indexing dashboard | Every URL Google ever met on sc-domain:clevrstart.com | 82 |
| URL Inspection API, read by search-read.ts | The 105 URLs in the sitemap | 25 |
The 57 in between are not mysteries.
I checked them with curl the same day. bookings.clevrstart.com answers 200 with a robots meta of noindex, nofollow, nocache, on purpose; agents.clevrstart.com answers 200 with noindex. ian and cms answer 307 to a login. The bare domain and http answer 308 to https://www. Those rows are the dashboard doing its job on URLs I never wanted ranked. The dashboard also refreshes every few days, while the API answers for the page as Google holds it now.
The script is search-read.ts, part of KhaordicOS, the operating system I run my businesses from. It reads the sitemap, calls the API once per URL, and writes a CSV with the verdict, the coverage state, the last crawl time and the canonical Google chose next to the one I declared. That last column is why I stopped worrying about the bilingual site being read as duplicate content: on both reads, zero URLs had a Google canonical different from their own. The full comparison of the two views, with the data for all 82 rows sorted into fix, ignore and wait, is what Search Console lies by omission: the dashboard versus the API shows; this column is about the clock.
Shape One: The Sitemap Error (flowingkhaos, 6 Hours)
I run flowingkhaos.com as a static Astro site on Cloudflare Workers. In early October it had 26 URLs in its sitemap.
| Read (UTC) | Sitemap | Submitted and indexed | Duplicate without user-selected canonical | Unknown |
|---|---|---|---|---|
| 2026-10-07 22:13 | 26 slash addresses | 1 | 21 | 4 |
| 2026-10-08 00:22 | 26 slashless addresses | 24 | 0 | 2 |
| 2026-10-15 17:10 | 36 | 34 | 0 | 1 (+1 discovered) |
One indexed page to 24 in six hours. Google crawled nothing in those six hours; the last-crawl dates in the CSV were all September’s. What changed was the sitemap. Every page answered at two addresses, /column and /column/, joined by a 307 from Cloudflare’s assets layer, before any of my code ran. A 307 is a temporary redirect, so Google kept both addresses, chose the slashless one and indexed it. The sitemap submitted the slash one. So every sitemap URL was a “duplicate” of a page Google already held under the other spelling. The pages had been indexed for weeks. The sitemap was the only thing on the site that did not know.
I wrote the repair up, step by step, in the Astro trailing slash fix, and the data there shows the four changes: one URL form everywhere, a 301 at the Cloudflare zone, Always Use HTTPS, HSTS, a lastmod on every sitemap entry and a dated TechArticle node on every page. The investigation page shows the part I got wrong first, with the data from each attempt: three commits fixed the canonical and the links and moved the build to one file per page, and the 307 was still there, because it came from the edge, not from Astro. The zone settings were confirmed live on 2026-10-15 with one curl each: /column/ answers 301, http answers 301, the HSTS header is on the home page.
The reading I care about is the third row. Ten pages were published after the fix, and all ten were indexed by the 2026-10-15 read. That is the first clean sample I have of “nothing broken, publish, wait”, and the wait was under a week for every one of them. I will not turn ten pages into a law. I will say it matches the 48-hour expectation more than it contradicts it. Impressions moved too, from 25 in September to 74 in the first half of October, but that is context, not the claim of this column.
Dashed line: 26 sitemap URLs, 26 pages
Source: Our own measurements
Shape Two: The Recrawl Delay (clevrstart, 19 to 80 in Eight Days)
I run clevrstart.com as a Next.js site on Vercel, English at the root and French under /fr, 105 URLs in the sitemap.
| Read (UTC) | URLs | Submitted and indexed | Discovered, not indexed | Crawled, not indexed | Unknown to Google |
|---|---|---|---|---|---|
| 2026-10-07 18:21 | 103 | 19 | 64 | 5 | 15 |
| 2026-10-15 16:37 | 105 | 80 | 16 | 5 | 4 |
Nothing was broken in the way flowingkhaos was broken. Zero canonical mismatches on either read. The pages answered 200 to Googlebot with the full text server-rendered. Google knew 64 of them existed and had not bothered to fetch them. That is the shape most people mean when they ask how long indexing takes: the site is fine, and Google is not coming.
On or about 2026-10-07 I clicked Validate Fix on 77 URLs in the dashboard. I did not note the time, so treat the date as my recollection. The recrawls in the 2026-10-15 CSV are dated 2026-10-12 to 2026-10-15, after the click. The count went from 19 to 80. I will state the coincidence and not the cause, because I changed other things in the same week, and because the pages that did not move tell me validation was not the lever.
Those pages are the five English service pages: /services/ai-agent, /services/chatbot, /services/booking-software, /services/blog and /services/professional-website. Status “Crawled, currently not indexed” on both reads. Last crawl 2026-08-28 or 29. Their French twins under /fr/services are indexed. Validate Fix asks Google to re-check a decision. For a page it had not fetched, a fetch changes the decision, and 48 of the 64 moved. For a page it had fetched and declined, re-checking the same page returns the same verdict, and all five stayed where they were. Request Indexing is a different button: it asks for a fresh fetch of the page as it is now. It only makes sense after the page has changed, which is why I have not pressed it yet.
Dashed line: 105 sitemap URLs, 105 URLs
Source: Our own measurements
Why Some Pages Stall: Crawl Refresh, Links and Sitemap Hygiene
I pulled the crawl stats for 2026-09-25 to 10-03. Googlebot visited clevrstart on 2 of those 9 days, with 10 and 19 requests. 96.5 percent of those requests were marked refresh, meaning a return to a page Google already had; 3.5 percent were discovery, a first fetch of something new. On a site that had just published dozens of pages, Google was spending almost its whole visit re-reading the old ones. Google’s crawling documentation says crawl demand is set by how popular a URL is and how stale Google thinks its copy is. Popular and stale are both measured from links and dates. The site was giving Google neither.
Links first. On 2026-10-15 I crawled the live site for links to service pages. The home page, /tools, /info, /about and /work carried zero. Only /services linked them, twice each, and /pricing once each; /industries linked one. Five pages with no inbound link from any indexed page except the catalogue, and the catalogue itself was not indexed. A page nothing links to is a candidate for the stall, and these five were the clearest case on the site. The fix shipped the same day as the read: a Services list in the footer of every page, seven links in English and eight in French, commit 694d211, live within the hour.
Dates next. On 2026-10-14 only 31 of the 105 sitemap entries carried a lastmod. The old sitemap addresses, /sitemap-index.xml, /fr/sitemap.xml and /sitemap-0.xml, all answered 404 and still showed up in PostHog hits, so something still asks for them. Both are on the list.
Canonicals last. The four legal pages, privacy and terms in both languages, emitted a relative canonical and no hreflang. Fixed in commit 605cba5 on 2026-10-14, verified live the next day. Three pages with no translation sibling carry only a self canonical, which is correct.
Treat this as a checklist, not a verdict. Each one is checkable in an afternoon, and each one is a reason for Google to come back sooner than “a few weeks”.
- Sitemap:
curl -s https://your-site/sitemap.xml | grep -c "<lastmod>"against the number of<loc>entries; every entry should carry a true date. In Search Console, Sitemaps, remove any submission that now answers 404. - Canonical:
curl -s https://your-site/page | grep -o '<link rel="canonical"[^>]*>'on one page per template; it must be absolute and point at itself. - Noindex:
curl -sI https://your-site/page | grep -i x-robots-tagandcurl -s https://your-site/page | grep -io '<meta name="robots"[^>]*>'; anything with noindex on a page you want ranked is the whole problem. - Internal links:
curl -s https://your-site/ | grep -o 'href="/services/[^"]*"' | sort | uniq -cfrom the home page and the pages Google already indexed; a page with zero inbound links from indexed pages goes to the top of the list. - Then, and only then, URL Inspection in Search Console, Request Indexing, one URL at a time, and write down the time.
The Test: Five Service Pages, a Clock, and What I Will Publish
As I write this, on the evening of 2026-10-15, the five English service pages, plus /services and /fr/services/referencement-local, which the API lists as unknown even though both answer 200, are waiting for one click: Request Indexing, in URL Inspection, one URL at a time. The footer links are live. The clock starts at the click.
The dates, as they land. Request Indexing clicked: not yet. First recrawl seen in the API: pending. First page indexed: pending. All five indexed: pending. First non-brand impression on any of the five: pending. This block is updated from the same CSV, and nothing in it is estimated.
No result is stated here because none exists yet. The Indexing API is not a shortcut: Google restricts it to JobPosting and BroadcastEvent pages. Request Indexing in the console is the only lever, and the method behind every number here, from the first API read to that click, is what how to get google to index your site shows, with the same CSV columns.
Now the vendor numbers, because you will meet them. Alev Digital’s guide reports an average turnaround of 3 to 5 days with no published sample. CrawlWP reports 24 to 72 hours for established sites, from a self-reported “200+ pages” with no dates. ClickRank’s data gives “a few hours to several weeks”, the non-answer the question keeps producing. I disagree that any of these tells you your own timeline. An average from an unknown sample is a mood, not a number. My ten post-fix pages are a tiny sample too, but they are dated, per URL, and checkable.
One warning from my own history. In 2024 I bought four cheap domains, pointed a Medium article’s canonical at my unindexed site, added the site to their sameAs and cross-linked them. Impressions went from nothing to thousands a month; clicks stayed few. I kept no export, so grade it as memory. I would not do it today. The reason I read the API weekly, which Why the Search Console API lives in my operating system explains with the data it reads, is so I never guess like that again.
The two-to-five-week ranking figure stays labelled as experience. Do not wait. Check the sitemap, the canonical, the noindex and the internal links today. The clock only runs on a page that is ready.
Sources
- Google Crawling and Indexing | Google Search Central | Documentation | Google for Developers
- In-Depth Guide to How Google Search Works | Google Search Central | Documentation | Google for Developers
- How long does it take for Google to index a new website? - Google Search Central Community
- Page indexing report - Search Console Help
- Google Search Console Request Indexing: Limits, Time, Steps & Fixes (2026)
- How Long Before Google Index a New Website & Page?
- Google Index Rate: How to Speed Up Crawling in 2026
- SEO in the age of AI: get your pages indexed, from the API
- Search Console lies by omission: the dashboard versus the API
- Why the Search Console API lives in my operating system
- Astro trailing slash on Cloudflare: fix the 307 and sitemap duplicates
- Astro trailing slash on Cloudflare: fix the 307 and sitemap duplicates — flowingkhaos
- Investigation — Astro trailing slash on Cloudflare: fix the 307 and sitemap duplicates
Questions, answered
- Why is my page crawled but not indexed?
- If the status is "Crawled, currently not indexed", Google fetched the page and declined it. In the article's data, five such service pages stayed unchanged after Validate Fix, because re-checking a page Google had already fetched and declined returned the same verdict.
- What should I check before waiting for Google to index my page?
- Check four things the same day: every sitemap entry carries a true lastmod, the canonical is absolute and points at itself, no page you want ranked has noindex, and the page has inbound internal links from pages Google already indexed.